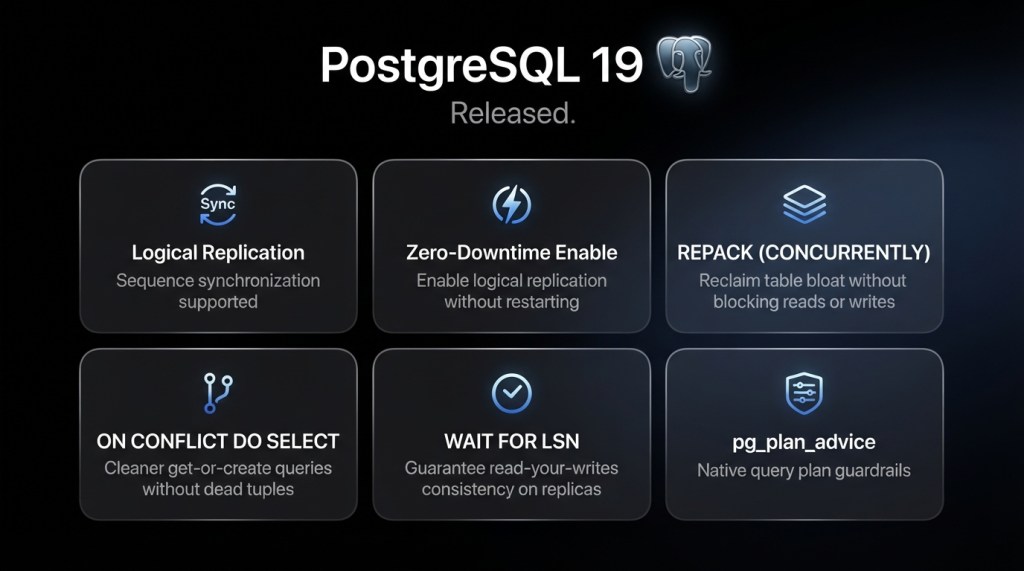
PostgreSQL 19 was released yesterday 19-Nov-2026 Some important features in this release :
🔹 Logical replication supports sequence synchronization 🔹 Logical replication can be enabled without restarting 🔹 REPACK (CONCURRENTLY) for reclaiming table bloat without blocking reads/writes 🔹 ON CONFLICT DO SELECT for cleaner get-or-create queries without dead tuples 🔹 WAIT FOR LSN to guarantee read-your-writes consistency on replicas 🔹 Native query plan guardrails with pg_plan_advice
You can spin up a quick container using:
docker run -d \
--name postgres19_server \
-p 0.0.0.0:5432:5432 \
-v postgres19_data:/var/lib/postgresql \
-e POSTGRES_USER=postgres \
-e POSTGRES_PASSWORD='YourPassword321##' \
-e POSTGRES_DB=demodb \
--restart always \
postgres:19
## Connect and check :
docker exec -it postgres19_server psql -U postgres -d postgres

## To remove the container :
docker rm -f postgres19_server
PostgreSQL is much more than a conventional relational database. With the right extensions, the same core engine can become a vector store, a time-series platform, a geospatial database, an analytical engine, an extension laboratory, or the data layer behind an AI agent.
In this hands-on lab, I run several PostgreSQL personalities side by side with Docker, then connect one of them to a secured PostgreSQL Model Context Protocol (MCP) server. The aim is not to declare one image “best.” It is to demonstrate just how broad the PostgreSQL ecosystem has become, and to show the Docker details that make a multi-image lab reliable.
Lab, not production blueprint: these examples prioritize learning and isolation. Before production use, add backups, monitoring, resource limits, TLS, a secrets manager, tested upgrades, and a deliberately designed high-availability architecture.
What we are building
Container
Image
Capability
Host port
Persistent volume
postgres18_server
postgres:18
Vanilla PostgreSQL baseline
5432
pg18_vanilla_data
postgres_pgvector18
pgvector/pgvector:0.8.4-pg18-trixie
Vector similarity search
5433
pgvector18_data
postgres_timescale18_node1
timescale/timescaledb-ha:pg18
Time-series plus vector extensions
5434
timescale18_node1_data
postgres_timescale18_node2
timescale/timescaledb-ha:pg18
Second independent TimescaleDB instance
5435
timescale18_node2_data
postgres_pglayers18
ghcr.io/pglayers/pglayers-full:18
Large extension catalogue
5436
pglayers18_data
postgres_ai_exts17
postgresai/extended-postgres:17-0.7.0
PostgresAI/DBLab extension set
5437
postgresai17_data
postgres-mcp
postgres-mcp-server:latest
Agent-safe database discovery and diagnostics
8899
None
Every database receives a unique host port and a unique volume. Inside the Docker network, however, every PostgreSQL container still listens on its normal container port, 5432.
Prerequisites and safety
Docker Desktop, or Docker Engine plus the Compose plugin on Linux.
Enough disk space for six independent database clusters.
At least 8 GB of RAM if several extension-heavy images will run together; stop containers you are not actively testing.
psql, pgAdmin, or DBeaver if you want to connect from the host.
Node.js 18 or newer, including npm/npx, on the computer where Claude Desktop runs the mcp-remote bridge.
Node.js 20 or newer if you rebuild or test the PostgreSQL MCP server source outside Docker.
All passwords and tokens below are placeholders. Generate new values for your own lab. Never paste a real MCP bearer token into a blog post, source repository, screenshot, or shared configuration file.
Set reusable lab variables (Add it to .bash_profile)
# Choose the bootstrap administrator used by the standard PostgreSQL images.
export POSTGRES_ADMIN_USER='my_admin_user'
# Replace this value before running the lab. Use a long, unique password.
# This is the application database created during first initialization.
export POSTGRES_DATABASE='my_database'
# Wait up to two minutes for a container to accept PostgreSQL connections.
# Arguments: container name, database role, and database name.
wait_for_postgres() {
container_name="$1"
role_name="$2"
database_name="$3"
for attempt in $(seq 1 60); do
if docker exec "$container_name" \
pg_isready -U "$role_name" -d "$database_name" >/dev/null 2>&1; then
return 0
fi
sleep 2
done
docker logs --tail 100 "$container_name"
return 1
}
# Confirm that Docker is available before creating anything.
docker version
docker ps
Environment variables are convenient for a lab, but they remain visible to processes in the shell and can appear in container metadata. Use Docker secrets or your platform’s secret manager for production.
The Docker foundation that prevents most PostgreSQL problems
Create one private network and one volume per server
# Create a user-defined bridge network if it does not already exist.
# Create independent persistent storage for each PostgreSQL personality.
docker volume create pg18_vanilla_data
docker volume create pgvector18_data
docker volume create timescale18_node1_data
docker volume create timescale18_node2_data
docker volume create pglayers18_data
docker volume create postgresai17_data
Never share PGDATA. Mounting one data directory into two PostgreSQL containers can corrupt the cluster. A different image or major version does not make the files interchangeable.
Understand the three image-specific storage paths
Image family
Correct container mount target
Why
PostgreSQL 18, pgvector PG18, pglayers PG18
/var/lib/postgresql
PostgreSQL 18 stores the cluster below a version-specific subdirectory such as /var/lib/postgresql/18/docker.
TimescaleDB HA PG18
/home/postgres/pgdata
The HA image defines PGDATA=/home/postgres/pgdata/data. Mounting the parent preserves the version’s complete packaged data area.
PostgresAI Extended PostgreSQL 17
/var/lib/postgresql/data
This is the image’s declared PGDATA/VOLUME. The lab uses a fresh named volume with volume-nocopy so initialization begins in an empty target.
Common docker run parameters
Parameter
Purpose
--detach
Runs the container in the background and prints its container ID.
--name NAME
Assigns a stable name used by docker exec, logs, health checks, and Docker DNS.
--network postgres-lab
Places the container on the private user-defined network. Other containers can reach it by name.
--publish 127.0.0.1:H:C
Maps host port H to container port C, but only on host loopback. Use an SSH tunnel for remote access.
--volume VOLUME:PATH
Persists database files outside the writable container layer.
Uses the explicit mount syntax and prevents Docker from pre-populating a new volume with files already present at the image path.
--env NAME=value
Supplies initialization or runtime settings. POSTGRES_* initialization settings only apply when PGDATA is empty.
--shm-size=1g
Raises shared memory above Docker’s small default, useful for parallel queries and index builds.
--health-cmd
Defines the command Docker uses to test database readiness.
--health-interval
Controls how often Docker runs the health check.
--health-timeout
Limits how long one health check may run.
--health-retries
Sets how many consecutive failures make the container unhealthy.
IMAGE
Selects the exact PostgreSQL distribution and tag.
postgres -c name=value
Overrides the image command and passes a startup-only PostgreSQL setting directly to the server.
Related command-line flags and shell syntax
Flag or syntax
Purpose
docker network inspect NAME
Checks whether a named network already exists and displays its metadata.
docker network create NAME
Creates a user-defined network with built-in container-name DNS.
docker volume create NAME
Creates a Docker-managed persistent volume.
docker exec --interactive
Keeps standard input open so psql can read a heredoc or accept input.
docker exec --tty
Allocates a terminal for a human-driven interactive psql session.
docker logs --follow
Streams new log records until you press Ctrl+C.
docker logs --tail N
Shows only the newest N log lines.
docker logs --since 2m
Shows logs produced during the last two minutes.
docker inspect --format TEMPLATE
Extracts a selected value, such as health status, from Docker metadata.
docker update --restart=unless-stopped
Adds a restart policy to a verified container without recreating it.
docker restart NAME
Stops and starts an existing container, preserving its command, environment, mounts, and published ports.
docker manifest inspect --verbose
Displays the platforms and detailed manifest data published for an image tag.
docker build --tag NAME .
Builds the Dockerfile in the current directory and assigns the resulting image a name and tag.
docker compose config
Resolves variables and validates the Compose model before deployment.
docker compose up --detach
Creates or reconciles the Compose services and leaves them running in the background.
psql -h HOST
Selects the database host; omitting it normally uses a local Unix socket.
psql -p PORT
Selects the PostgreSQL TCP port.
psql -U ROLE
Selects the PostgreSQL login role.
psql -d DATABASE
Selects the database to connect to.
psql -W
Forces a password prompt before connecting.
psql -c SQL
Runs one SQL command and exits.
psql -v ON_ERROR_STOP=1
Makes scripted psql stop immediately when any statement fails.
ssh -N
Creates forwarding only and does not run a remote shell command.
ssh -L LPORT:HOST:RPORT
Forwards a local port through SSH to a host and port visible from the remote machine.
ssh -i KEY
Selects the private key used to authenticate to the remote host.
openssl rand -hex N
Generates N random bytes and encodes them as twice as many hexadecimal characters.
[ -z "${VAR:-}" ]
Tests safely whether a shell variable is unset or empty.
${VAR:?MESSAGE}
Stops the current command with MESSAGE when a required variable is unset or empty.
chmod 600 FILE
Allows only the file owner to read or write a secret-bearing configuration file on POSIX systems.
>/dev/null 2>&1
Suppresses both normal and error output from the idempotent network-existence check.
COMMAND_A || COMMAND_B
Runs the second command only if the first command fails.
wait_for_postgres CONTAINER ROLE DATABASE
Calls the helper defined above, retrying pg_isready for up to two minutes and printing recent logs if startup fails.
<<'SQL'
Feeds a literal heredoc into psql; the quoted marker prevents shell expansion inside the SQL body.
I deliberately omit a restart policy during the first boot. Once a database is healthy, enable unless-stopped. This makes startup errors visible instead of hiding them inside a rapid restart loop.
Lab 1: Vanilla PostgreSQL 18—the baseline
The official PostgreSQL image is the control group for the lab: no third-party extensions, no custom process supervisor, and the standard PostgreSQL 18 data layout.
# Start vanilla PostgreSQL 18 on host port 5432.
# The database is reachable by other lab containers as postgres18_server:5432.
# Reuse the volume created earlier instead of making a project-prefixed volume.
volumes:
pg18_vanilla_data:
external: true
Compose key
Purpose
services / db
Defines the application services and gives this PostgreSQL service its Compose-local name.
image
Selects the container image and tag.
container_name
Assigns the same stable Docker name used by the docker run example.
networks
Attaches the service to postgres-lab.
ports
Publishes host-loopback port 5432 to container port 5432.
environment
Passes the three shell variables into the container. Compose resolves the single-dollar expressions.
shm_size
Allocates 1 GB for the container’s /dev/shm.
healthcheck.test
Runs pg_isready through a container shell. Double dollar signs defer variable expansion to that shell.
interval, timeout, retries
Set the health-check cadence, per-check limit, and failure threshold.
volumes
Mounts the persistent volume at the PostgreSQL 18 parent data directory.
external: true
Tells Compose to reuse the pre-created network and volume rather than make project-prefixed replacements.
# Validate the Compose file, then start it in detached mode.
docker compose config
docker compose up --detach
After the service is healthy, add restart: unless-stopped beneath container_name, then apply the edited Compose model:
# Reconcile the service after adding the verified restart policy.
docker compose up --detach
Lab 2: pgvector—PostgreSQL as a vector database
The pgvector image extends the official PostgreSQL image with the vector data type, exact distance operations, and approximate indexes such as HNSW and IVFFlat. The pinned tag below provides pgvector 0.8.4 on PostgreSQL 18 and Debian Trixie.
# Start an independent pgvector cluster on host port 5433.
Lab 3: TimescaleDB—time-series and high-performance vectors
The TimescaleDB HA image combines PostgreSQL with TimescaleDB and other packaged extensions. It uses PGDATA=/home/postgres/pgdata/data, so the named volume is mounted at its parent, /home/postgres/pgdata, rather than the official image’s /var/lib/postgresql path.
Two containers do not automatically form a highly available cluster. The commands below create two independent instances for comparison and failover experiments. Patroni, a distributed configuration store, replication, and a routing layer require separate configuration.
# Start independent TimescaleDB instance 1 on host port 5434.
pglayers publishes PostgreSQL extensions as composable image layers and also provides a full profile containing more than fifty extensions. Although the project documents multi-architecture layer support, the live pglayers-full:18 tag resolved to Linux AMD64 only when this article was reviewed. Check the manifest again before using it on ARM64.
This image preloads many libraries that register background workers. PostgreSQL’s default worker limit is eight, while the pglayers test suite uses 64. The full profile also configures components around the canonical postgres role, so this lab intentionally keeps POSTGRES_USER=postgres. Because this walkthrough does not initialize DocumentDB, its internal PostgreSQL background worker is disabled to suppress the missing-role warning. This setting does not disable the separately preloaded MongoDB wire-gateway library.
# Start pglayers Full on host port 5436.
# max_worker_processes=64 prevents the extension workers exhausting the default pool.
# The DocumentDB worker is disabled until that extension is deliberately installed.
The full image makes extensions available; it does not mean every extension should be created in every database. Some extensions have background workers, database-role requirements, or mutual conflicts. Enable only what your experiment needs. To test DocumentDB, stop and recreate this container against the same named volume without the disabling -c option; command arguments cannot be changed by a simple restart. Then follow the project’s documented DocumentDB installation sequence in the configured postgres database.
Lab 5: PostgresAI Extended PostgreSQL 17
The postgresai/extended-postgres image is primarily designed for PostgresAI Database Lab workflows. Its default startup script expects an existing cluster and deliberately keeps the container alive if PostgreSQL stops. For a fresh standalone lab, appending postgres activates the inherited official initialization path. Mounting a brand-new named volume at the image’s declared PGDATA path with volume-nocopy guarantees an empty initialization target.
# Start the AMD64 PostgresAI PostgreSQL 17 image on host port 5437.
# Mount the image's declared PGDATA and prevent Docker from copying image-layer files.
# The final "postgres" argument is essential for first-run initialization.
If initdb reports that PGDATA “exists but is not empty,” do not delete files until you know what they are. Stop the container, inspect the volume, and use a new empty volume for a disposable lab. PostgreSQL will not initialize over unrelated or partial files.
Comparing the PostgreSQL personalities
Stack
Best suited to
Initialization
Architecture note
Main caution
Official PostgreSQL 18
Baseline relational and JSON workloads
Automatic on empty volume
Multi-architecture
Add extensions yourself
pgvector PG18
Embeddings and similarity search
CREATE EXTENSION vector
AMD64 and ARM64 tags available
One extension-focused image, not an AI platform by itself
TimescaleDB HA PG18
Time-series, telemetry, PostGIS, and vectorscale
Create/verify extensions per database
AMD64 and ARM64
Two containers are not automatically HA
pglayers Full PG18
Discovering and testing a wide extension catalogue
Create selected extensions per database
Current full tag: AMD64; verify the live manifest
Many preloaded workers; keep the postgres role and raise worker slots
PostgresAI Extended PG17
Database Lab and advanced extension experiments
Override the command with postgres for a fresh standalone cluster
Published tag is AMD64
Default startup assumes existing PGDATA
Connect with psql, pgAdmin, or DBeaver
From inside a database container, use the container’s normal port 5432—or omit the port entirely. From the host, use the mapped port from the lab table.
# From inside the vanilla container: local socket, no host port mapping involved.
# From the Docker host: connect to pglayers on host port 5436.
psql -h 127.0.0.1 -p 5436 \
-U postgres -d "$POSTGRES_DATABASE" -W
For pgAdmin or DBeaver, use host 127.0.0.1, the mapped host port, the configured database, and the matching user. On an EC2 host, keep Docker bound to loopback and use an SSH tunnel instead of opening every database port to the internet.
# Forward local laptop port 5432 securely to the EC2 host's loopback port 5432.
ssh -N \
-L 5432:127.0.0.1:5432 \
-i /absolute/path/to/key.pem \
ec2-user@YOUR_EC2_HOST
Add the PostgreSQL MCP server
The Postgres MCP Server exposes schema discovery, object inspection, bounded SQL execution, query-plan diagnostics, index recommendations, workload analysis, database monitoring, and optional Prometheus metrics. One MCP process connects to one PostgreSQL database URI. For simultaneous targets, each additional MCP instance needs its own Docker container name, host port, database role, Claude configuration key and URL, plus an allowed-origin entry matching that URL.
Build the MCP image
# Clone the MCP server and enter its repository before building.
# Option A: build an unchanged checkout from its tracked build output.
docker build --tag postgres-mcp-server:latest .
If you modify the TypeScript source, use the following validation-and-build path instead of the final build command above.
# Option B: install the locked dependencies, validate the source, and rebuild.
# If you edit TypeScript source, rebuild and test before rebuilding the image.
# These commands require Node.js 20 or newer on the host.
npm ci
npm run check
npm run test:unit
npm run build
docker build --tag postgres-mcp-server:latest .
Create a least-privilege database role
MCP_DB_MODE=restricted adds application-level safeguards, but PostgreSQL privileges remain the real security boundary. Do not connect the MCP service as a superuser.
# Generate a fresh URL-safe database password and keep it in this private shell.
# Hexadecimal output contains no URI delimiter characters.
export MCP_DB_PASSWORD="$(openssl rand -hex 24)"
# Stop before creating the role if OpenSSL failed.
: "${MCP_DB_PASSWORD:?OpenSSL did not generate an MCP database password}"
# Create the MCP role and grants as one fail-fast script.
# psql safely quotes the password and database-name variables in the SQL below.
-- Allow the role to connect to this database and inspect the public schema.
GRANT CONNECT ON DATABASE :"target_db" TO mcp_reader;
GRANT USAGE ON SCHEMA public TO mcp_reader;
-- Grant read access to current tables.
GRANT SELECT ON ALL TABLES IN SCHEMA public TO mcp_reader;
-- Grant read access to future tables created by this administrator.
ALTER DEFAULT PRIVILEGES IN SCHEMA public
GRANT SELECT ON TABLES TO mcp_reader;
SQL
Roles are local to a PostgreSQL cluster. Before pointing MCP at pgvector, TimescaleDB, pglayers, or PostgresAI, repeat the dedicated-role and grant step in that target cluster with its administrator and database name. Do not merely change the hostname in the URI.
Optional: grant deeper MCP observability
The least-privilege role above can inspect schemas and selected data, but some workload and monitoring tools will return partial results. The vanilla image does not preload pg_stat_statements, and ordinary roles cannot see every session’s query text. If that wider visibility is acceptable in your lab, enable it explicitly:
# Configure the bundled statistics library; this setting needs a restart.
CREATE EXTENSION IF NOT EXISTS pg_stat_statements;
GRANT pg_monitor TO mcp_reader;
SQL
pg_monitor exposes cluster-wide monitoring information, so grant it only after reviewing that visibility. HypoPG is not packaged in the vanilla image; MCP can still recommend indexes there, but hypothetical-index validation remains unavailable unless you choose an image that supplies HypoPG.
Run the MCP server on the private Docker network
# Generate a fresh 64-character bearer token for this MCP instance.
# Keep it out of shell history, recordings, screenshots, and source control.
# Stop immediately if OpenSSL failed and left the token empty.
: "${POSTGRES_MCP_TOKEN:?OpenSSL did not generate an MCP token}"
# Start a restricted, bearer-authenticated Streamable HTTP MCP endpoint.
# Docker DNS resolves postgres18_server directly on the private network.
docker run --detach \
--name postgres-mcp \
--network postgres-lab \
--publish 127.0.0.1:8899:8899 \
--read-only \
--tmpfs /tmp \
--security-opt no-new-privileges:true \
--env "DATABASE_URI=postgresql://mcp_reader:${MCP_DB_PASSWORD:?MCP_DB_PASSWORD is not set}@postgres18_server:5432/${POSTGRES_DATABASE:?POSTGRES_DATABASE is not set}?sslmode=disable" \
--env PGSSLMODE=disable \
--env MCP_TRANSPORT=http \
--env MCP_HTTP_HOST=0.0.0.0 \
--env MCP_HTTP_PORT=8899 \
--env MCP_HTTP_PATH=/mcp \
--env MCP_DB_MODE=restricted \
--env "MCP_AUTH_TOKEN=${POSTGRES_MCP_TOKEN:?POSTGRES_MCP_TOKEN is not set}" \
Claude needs the same bearer token. While this private shell or SSH session is still open, transfer it directly into your password manager or secure clipboard. If you must display it, do so once in a private, non-recorded terminal and clear the terminal scrollback afterward:
# Display the token only in a private terminal so it can be copied to Claude.
printf '%s\n' "$POSTGRES_MCP_TOKEN"
MCP parameter reference
Parameter
Purpose
--network postgres-lab
Lets the MCP container reach the selected database by container name and internal port 5432.
--publish 127.0.0.1:8899:8899
Exposes MCP only on host loopback. It is not directly reachable from the network.
--read-only
Makes the MCP container filesystem read-only.
--tmpfs /tmp
Provides a temporary writable in-memory directory required by some runtime operations.
--security-opt no-new-privileges:true
Prevents processes from gaining additional Linux privileges.
DATABASE_URI
Selects exactly one PostgreSQL target. Use container DNS and port 5432 on the shared network.
PGSSLMODE=disable
Disables TLS only for this trusted, private container network. Use certificate verification for remote databases.
MCP_TRANSPORT=http
Enables Streamable HTTP. The legacy value sse is only an alias; legacy SSE endpoints require a separate opt-in.
MCP_HTTP_HOST=0.0.0.0
Listens on all interfaces inside the container. The host-side publish remains safely bound to 127.0.0.1.
MCP_HTTP_PORT=8899
Sets the HTTP listener port inside the container.
MCP_HTTP_PATH=/mcp
Sets the Streamable HTTP MCP endpoint path.
MCP_DB_MODE=restricted
Enables read-oriented SQL inspection, read-only transactions, row limits, and timeouts.
MCP_AUTH_TOKEN
Sets the static Bearer token. The server requires at least 16 characters.
MCP_ALLOWED_HOSTS
Restricts accepted HTTP Host values when the internal listener is non-loopback.
MCP_ALLOWED_ORIGINS
Restricts browser-style Origin values when an Origin header is present.
# Confirm the MCP process, database connection, and readiness endpoint.
docker logs postgres-mcp
curl http://127.0.0.1:8899/healthz
curl http://127.0.0.1:8899/readyz
# Enable automatic restart only after readiness succeeds.
To point MCP at another lab server, first create mcp_reader and its grants in that cluster, then recreate the MCP container with that target’s hostname, database, and generated password in DATABASE_URI. The private-network port remains 5432. A simultaneous second MCP target also needs a unique --name, a different host-side published port, a matching allowed origin, and a distinct client configuration entry.
Configure Claude Desktop
Claude Desktop starts the community mcp-remote bridge as a local process and forwards it to the loopback-only Streamable HTTP endpoint. The example pins version 0.1.38, verified when this article was reviewed, instead of downloading an unspecified future release. Replace the placeholder with the token generated above; the value must include the Bearer prefix.
-y allows npx to install/run the pinned bridge without an interactive confirmation.
--allow-http is acceptable here only because the endpoint is local loopback.
--transport http-only selects Streamable HTTP.
--header adds the required Authorization header.
If Claude cannot locate npx, replace it with the absolute path returned by command -v npx.
Restrict the Claude configuration file to your account where the operating system supports POSIX permissions—for example, chmod 600 "$HOME/Library/Application Support/Claude/claude_desktop_config.json" on macOS. The token is still plaintext in that file, so do not share it. Completely quit and reopen Claude Desktop after changing the configuration. A cloud-hosted connector cannot reach 127.0.0.1 on your computer; this is a local Claude Desktop configuration.
MCP on EC2: tunnel it instead of publishing it
# Run this on the laptop that hosts Claude Desktop.
# It maps laptop port 8899 to the EC2 host's loopback-only MCP endpoint.
ssh -N \
-L 8899:127.0.0.1:8899 \
-i /absolute/path/to/key.pem \
ec2-user@YOUR_EC2_HOST
Claude still connects to http://127.0.0.1:8899/mcp. Do not open port 8899 in the EC2 security group merely to make the demo reachable.
Troubleshooting playbook
Symptom
Likely cause
Fix
port is already allocated
Two containers publish the same host port.
Use the unique host-port map in this article. Container port 5432 remains unchanged.
initdb: directory exists but is not empty
The mounted PGDATA contains files, perhaps from an earlier or incorrect mount.
Inspect it first. For a disposable lab, create a new empty volume.
Missing .s.PGSQL.5432 socket
PostgreSQL did not finish starting.
Run docker logs --tail 200 CONTAINER; do not treat a running container as proof of a running database.
Host port is listening but PostgreSQL refuses connections
Docker published the port even though the database process failed.
Check container health, logs, and pg_isready.
pglayers repeatedly says to increase max_worker_processes
The full profile exhausted PostgreSQL’s default worker pool.
Start it with postgres -c max_worker_processes=64.
pglayers reports role "postgres" does not exist
A custom POSTGRES_USER replaced the canonical bootstrap role while bundled workers expect postgres.
For a fresh full-profile lab, initialize with POSTGRES_USER=postgres.
DocumentDB worker role warning
The DocumentDB library is preloaded but its extension has not created the required role.
Create DocumentDB in its configured database or disable that background worker if DocumentDB is not part of the test.
PostgresAI container is up but PostgreSQL is not
The default DBLab-oriented script expects initialized PGDATA.
Use an empty PG17 volume and append postgres to the image command.
Changed POSTGRES_USER or POSTGRES_DB has no effect
The volume already contains an initialized cluster.
Change roles/databases with SQL, or initialize a new empty volume.
MCP cannot reach PostgreSQL
The URI uses localhost inside the MCP container.
Use the shared Docker network and the PostgreSQL container name.
MCP returns HTTP 401
The bearer token is missing, stale, or lacks the Bearer prefix.
Use the same generated token in the container and client header.
Claude rejects its configuration
Malformed JSON, missing closing brace, or unavailable npx.
Validate the JSON and use an absolute npx path if necessary.
Production hardening checklist
Pin immutable image tags or digests and test upgrades before deployment.
Use a secret manager rather than plaintext environment variables.
Bind database and MCP ports to private interfaces; prefer SSH tunnels, private networks, or VPN access.
Use TLS with hostname and certificate verification for remote PostgreSQL endpoints.
Give MCP a dedicated least-privilege PostgreSQL role; keep restricted mode enabled.
Do not enable EXPLAIN ANALYZE or unrestricted MCP mode without understanding that queries or writes will execute.
Add tested backups, restore drills, monitoring, WAL management, disk alerts, and capacity limits.
Do not call two standalone TimescaleDB containers “HA” until replication, leader election, routing, and failover have been configured and tested.
Prefer a deliberately composed extension image over an everything-enabled bundle for production.
Conclusion
This lab demonstrates why PostgreSQL earns the “Swiss Army knife” description. The core database remains familiar, while extensions change the workload it can address: pgvector adds similarity search, TimescaleDB adds time-series behavior, pglayers turns extension discovery into a composable workflow, PostgresAI packages a broad Database Lab toolset, and MCP makes PostgreSQL safely inspectable by AI clients.
The real lesson is not only PostgreSQL’s flexibility. It is that Docker isolation matters: unique ports, unique volumes, image-correct PGDATA paths, explicit health checks, canonical roles where an image expects them, and least-privilege connections. Get those foundations right and the PostgreSQL ecosystem becomes an unusually capable platform for experimentation.
Most migrations from on-prem PostgreSQL to Aurora rely on logical replication or AWS DMS directly from the source. But what if you want to reduce load on your production system, add a control layer, or deal with network constraints?
I recently explored an approach using an intermediary PostgreSQL instance on EC2.
This architecture is valid and commonly used in complex migrations, especially when you want to decouple source load, add transformation control, or work around network/security constraints.
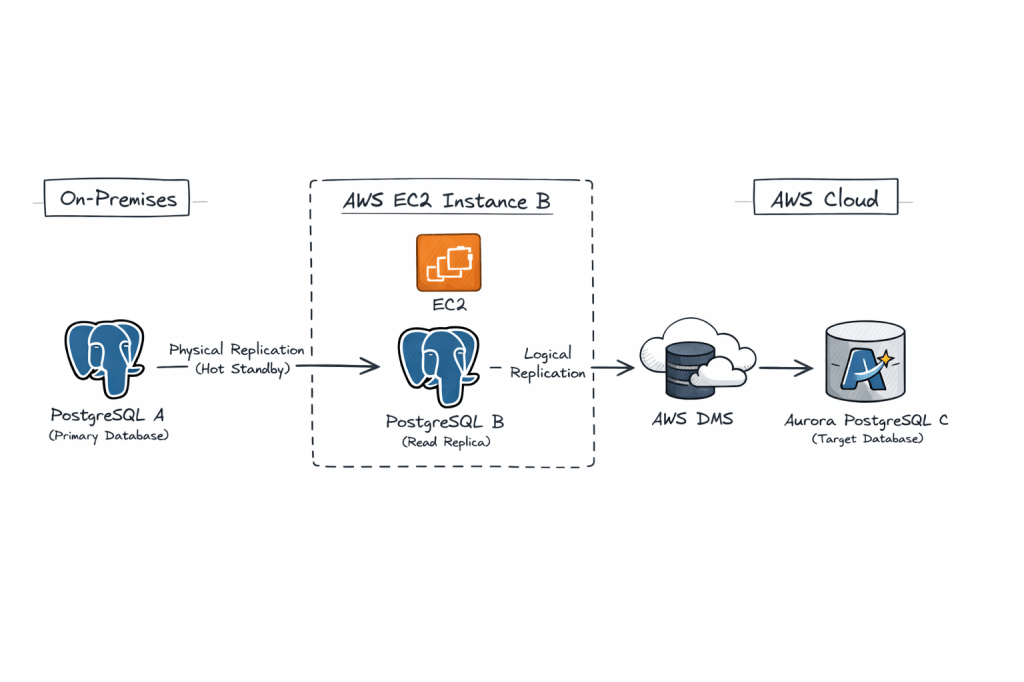
we’re essentially proposing a hybrid replication chain:
A (on-prem PostgreSQL) → B (EC2 PostgreSQL) via physical replication
B (EC2 PostgreSQL) → C (Aurora PostgreSQL) via logical replication / AWS DMS
Why this is interesting:
• Physical replication ensures a low-impact, byte-level copy from the source • Logical replication from the intermediary allows selective migration and transformation • The EC2 layer acts as a buffer, isolating production from migration tooling
Key benefits:
• Zero logical decoding overhead on production • Better control over migration scope • Improved fault isolation • Flexible transformation using DMS
Trade-offs:
• Increased replication lag due to chaining • More operational complexity • WAL retention needs careful monitoring • Logical decoding on standby requires newer PostgreSQL versions
This pattern is especially useful in regulated environments or where direct connectivity to AWS is restricted.
It is not the simplest design, but it is a powerful one when used in the right context.
Pre-Requisities on Both A and B
1. Ensure Port 5432 is added to Firewall whitelist on both hosts for ingress and also on the Security Group of the instance
✔ Direct A → Aurora is not feasible ✔ You want zero impact on source DB ✔ You need data transformation/filtering ✔ You want controlled cutover with buffer layer
Avoid it when:
✖ Simplicity is priority ✖ Low-latency replication required ✖ PostgreSQL version < 14
Blue-Green deployment for a Database service uses a Blue environment (Production) and creating a Green environment with it (Staging) and creating ongoing replication from the Production Blue environment to the staging environment.
A blue/green deployment works by creating a fully synchronized copy of your production database and running it as a separate staging environment.
In this article I will show how you can build a Blue-Green deployment for your OCI PostgreSQL for doing apps related testing.
High-level steps to Orchestrate a Blue-Green deployment strategy with OCI PostgreSQL
Via Logical Replication for Major Version Upgrades or App Performance/Regression Testing
Most DBAs & DevOps people are already familiar with the Blue-Green deployment methodology when deploying a new version of a service. OCI PostgreSQL does not natively support Blue-Green deployment as of when this article was written. But it is quite easy to setup using a few OCI native components and logical replication with pglogical (or OCI Goldengate)
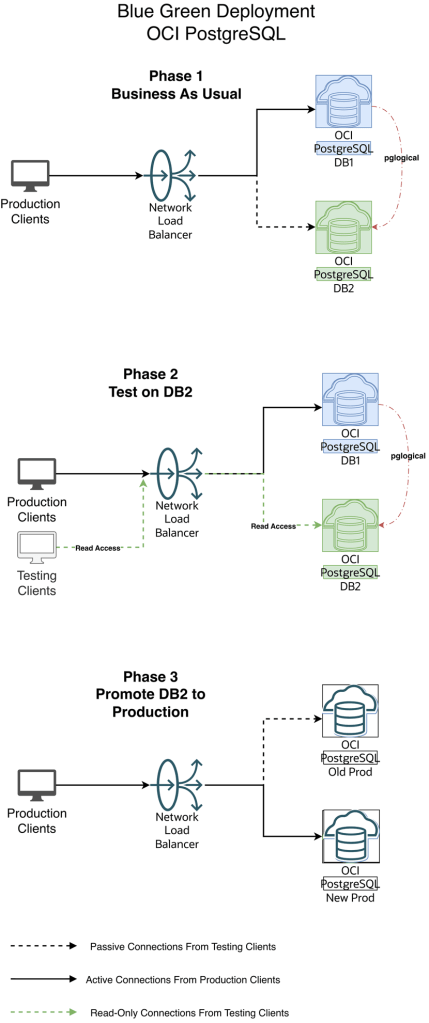
Diagram 1 — Blue-Green Workflow
1.Initial and One time setup:
a. Create an additional new version DB2 OCI PostgreSQL cluster
c.Create an OCI Network load balancer for their applications to connect to. This LB will act as a proxy to the actual database system.
d. Have the load balancer backend point to the primary endpoint ip address of the database system(say DB1)
2. When we have new changes, do initial load for OCI Postgres between DB1 to DB2 using any of the logical data migration utilities like pg_dump, pg_restore
3. Create publication and subscription from DB1 to DB2 using pglogical (or OCI Goldengate)
4. Have the app tests hit DB2 endpoint to perform read queries, validate and certify the changes
5. When DB2 appears ready for production consumption, orchestrate:
a. Pause any app activity and pause pglogical replication (optional) since pglogical is logical replication tool, the DB2 is always available in Read-Write mode. Just for App testing we are using read-only mode to avoid conflicts and complex scenario of reverse replication from DB2 to DB1
b. Update load balancer backend to the primary endpoint ip address of DB2
c. Stop the replication setup between DB1 and DB2 by stopping the publisher and subscribers
6. Production Client Apps are now connecting to the new Production environment (Green)
Step-By-Step Orchestration of Blue Green Deployment :
A. Setup
OCI PostgreSQL Database v15 which is the Blue environment aka Current Production
IP : 10.150.2.105
2. OCI PostgreSQL Database v16 which is the Green environment aka Staging
IP : 10.150.2.62
3. OCI Network Load Balancer with the 2 DB endpoints added as backend set fronted with a listener on tcp/5432
Listener
Backends
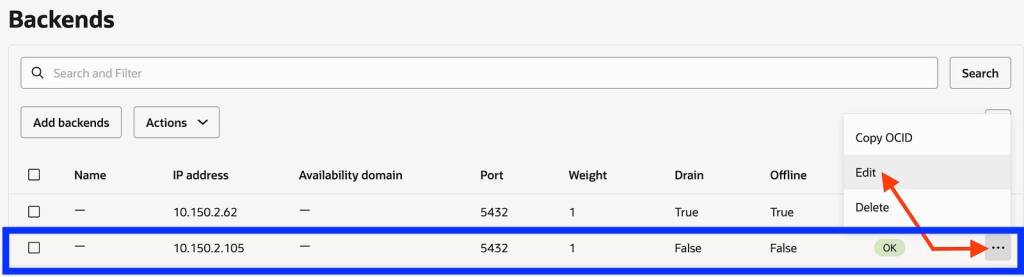
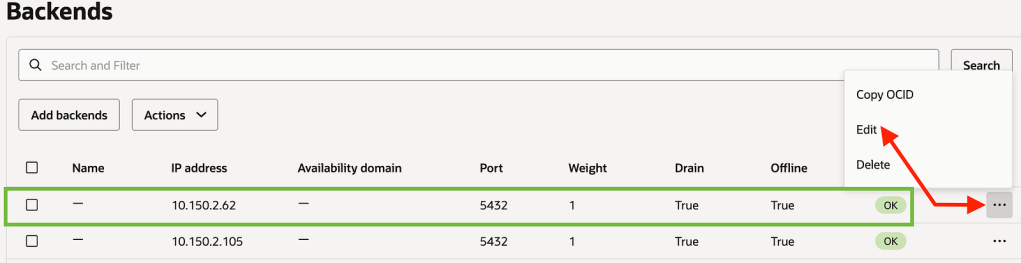
Make sure the Blue (Production) environment is active and the Green environment backend set is offline and drained.
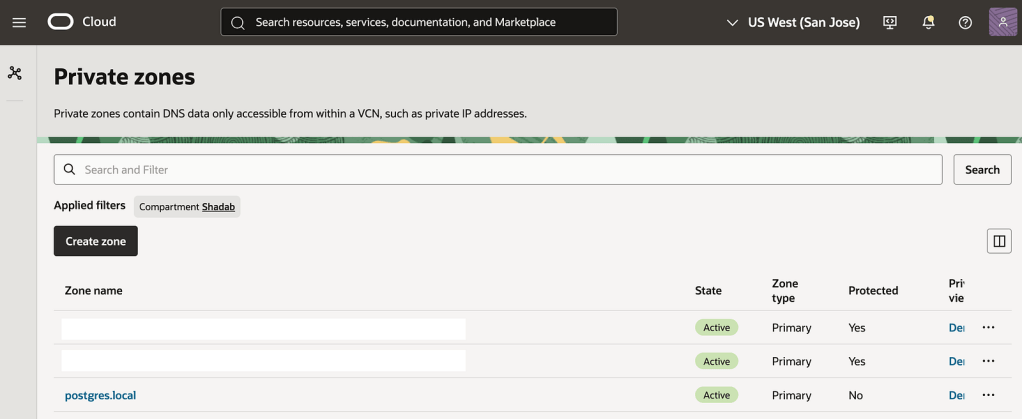
4. Create an OCI DNS Private zone in your VCN’s DNS resolver
In my case i call my private zone postgres.local
nlb-app.postgres.local is the main FQDN all apps will use to connect the backend database
nlb-app-blue.postgres.local is the FQDN for Blue Database and this is not used by App connections
nlb-app-green.postgres.local is the FQDN for the Green Database and this is used by the App stack which will perform the Read-only queries for validating the application performance.
We will use the OCI Network Load Balancers backend set to make the blue backend IP offline and activate green IP, This incurs a small outage (in seconds depending on TTL of the DNS resolver) where the App moves from connecting to Blue Database to the Final Green Database which is promoted as production.
################# — Source Blue v15 — #################
Hostname : primary.umiokgnhd4hlpov7xncfwymgxv4pgq.postgresql.us-sanjose-1.oci.oraclecloud.com Version : 15.12
— Run the following query to grant permissions on the source database to enable logical replication. —
CREATE EXTENSION pglogical;

show oci.admin_enabled_extensions ;
alter role postgres with replication;

grant EXECUTE on FUNCTION pg_catalog.pg_replication_origin_session_reset() to postgres ;

grant EXECUTE on FUNCTION pg_catalog.pg_replication_origin_session_setup to postgres ;

grant all on FUNCTION pg_catalog.pg_replication_origin_session_setup to postgres;
Note : postgres is the admin user created during the database setup process.
— Create the publisher node on the source database. —
node_name: Specify the name of the publisher to be created on the source database.

host: Enter the fully qualified domain name (FQDN) of the source database.

port_number: Provide the port on which the source database is running.

database_name: Specify the database where the publication will be created.
— Include all tables in the public schema to the default replication set. —
################# — Target Green v16 — #################
Hostname : primary.46mtfkxsj6337nqvx2de6gq3a57m4a.postgresql.us-sanjose-1.oci.oraclecloud.com Version : 16.8
— Run the following query to grant permissions on the target database to enable logical replication. —
CREATE EXTENSION pglogical;

show oci.admin_enabled_extensions ;
alter role postgres with replication;

grant EXECUTE on FUNCTION pg_catalog.pg_replication_origin_session_reset() to postgres ;

grant EXECUTE on FUNCTION pg_catalog.pg_replication_origin_session_setup to postgres ;

grant all on FUNCTION pg_catalog.pg_replication_origin_session_setup to postgres;
Note : postgres is the admin user created during the database setup process.
— Create the subscriber node on target database. —
node_name: Define the name of the subscriber on the target database.

host: Enter the fully qualified domain name (FQDN) of the target database.

port_number: Enter the port on which the target database is running.

database_name: Provide the name of the database where the subscription will be created.
— Create the Schema-only on Target Database. This can also be done with pg_dump and pg_restore or psql —
subscription_name: Provide the name of the subscription.

host: Provide the FQDN of the source database.

port_number: Provide the port on which the target database is running.

database_name: Provide the name of the source database.
Note: Be sure to use sslmode=verify-full and sslrootcert = /etc/opt/postgresql/ca-bundle.pem in subscription creation string to prevent any connection failures.
################# — Target Green v16 — ################# — Run the following statement to check the status of your subscription on your target database. —
select * from pglogical.show_subscription_status();
################# — Source Blue v15 — ################# — Run the following statement to check the status of your replication on your source database. —
Your Apps are now connecting to the v15 Blue Database via this Endpoint
$ alias | grep pgnlb

alias pgnlb='PGPASSWORD=YourPasswor@123# psql -h nlb-app.postgres.local -U postgres -d postgres'
$ pgnlb


psql (17.7, server 15.12)

SSL connection (protocol: TLSv1.2, cipher: ECDHE-RSA-AES256-GCM-SHA384, compression: off, ALPN: none)

Type "help" for help.
## The Server we're connecting to is the v15.12 which is Blue
Scenario 2 — The replication is ongoing to DB2 and Your Testing Clients connect to DB2
Your Testing Apps are now connecting to the v16 Green Database via this Endpoint
$ alias | grep pggreen

alias pggreen='PGPASSWORD=YourPasswor@123# psql -h nlb-app-green.postgres.local -U postgres -d postgres'
$ pggreen

psql (17.7, server 16.8)

SSL connection (protocol: TLSv1.2, cipher: ECDHE-RSA-AES256-GCM-SHA384, compression: off, ALPN: none)

Type "help" for help.
Scenario 3 — The replication is stopped to Green (DB2), Green is promoted as Production and Your Production Clients connect to Green environment
Flip the OCI Network Load Balancer Backend Set (Make sure TTL is as low as possible)
Make the current blue IP backend offline and drain it
Save the changes. In this brief moment there is no connectivity from App to DB and your business users should be notified that there will be a brief outage
If you run pgnlb it will hang as there is no backend IP to connect to
[opc@linux-bastion ~]$ pgnlb
Now let us make the Green environment as online from the backend set and Connect the Apps back.
Save Changes
Now connect with pgnlb
[opc@linux-bastion ~]$ pgnlb

psql (17.7, server 16.8)

SSL connection (protocol: TLSv1.2, cipher: ECDHE-RSA-AES256-GCM-SHA384, compression: off, ALPN: none)

Type "help" for help.
You can see that pgnlb is now connecting to the new upgraded v16 version which is the Green environment
Some Advantages of Blue-Green testing:
Perform testing of major version upgrades (e.g. pgsql 13 -> 15)
Major patching/testing with a production-like copy
Validate application behavior against new database versions/configs
Support phased testing (read-only validation, performance testing)
Decouple app endpoint from database endpoint using a Load Balancer
Conclusion
We’ve successfully created a end-to-end Blue-Green Testing Methodolgy for OCI PostgreSQL
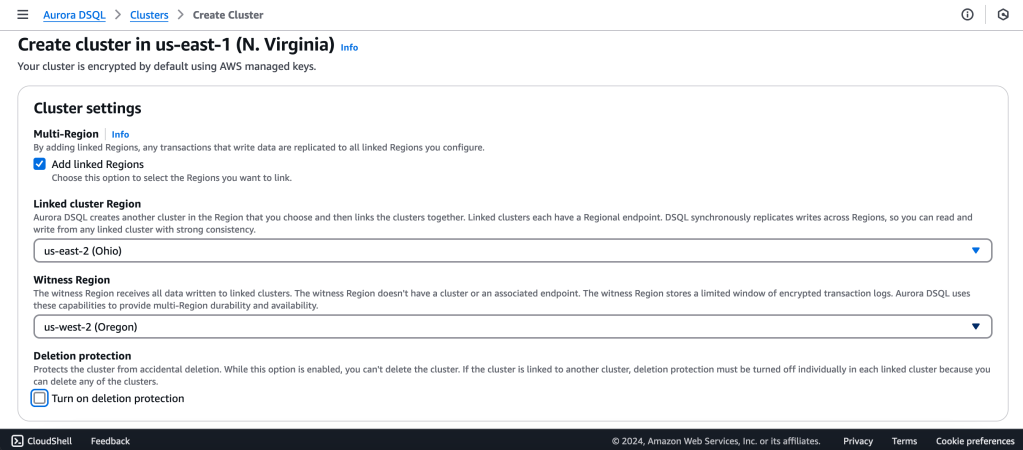
Amazon just launched the new Distributed SQ> Aurora Database today.
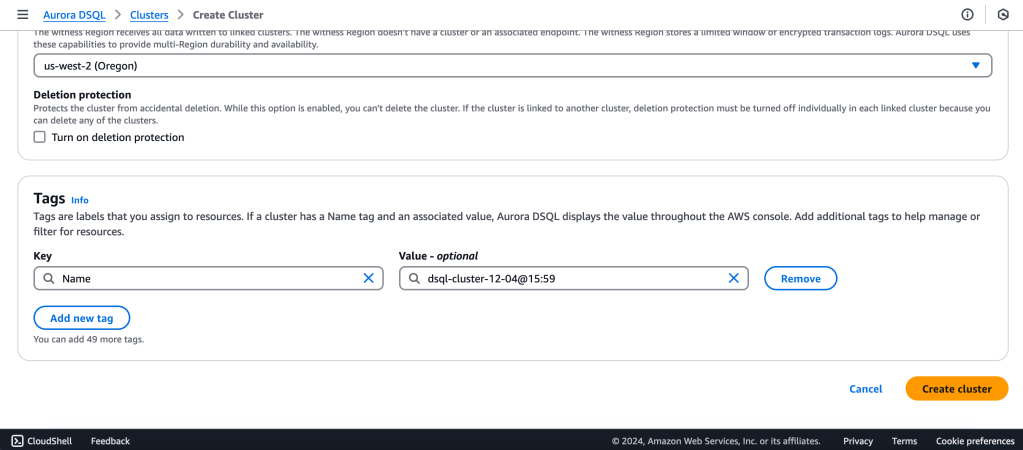
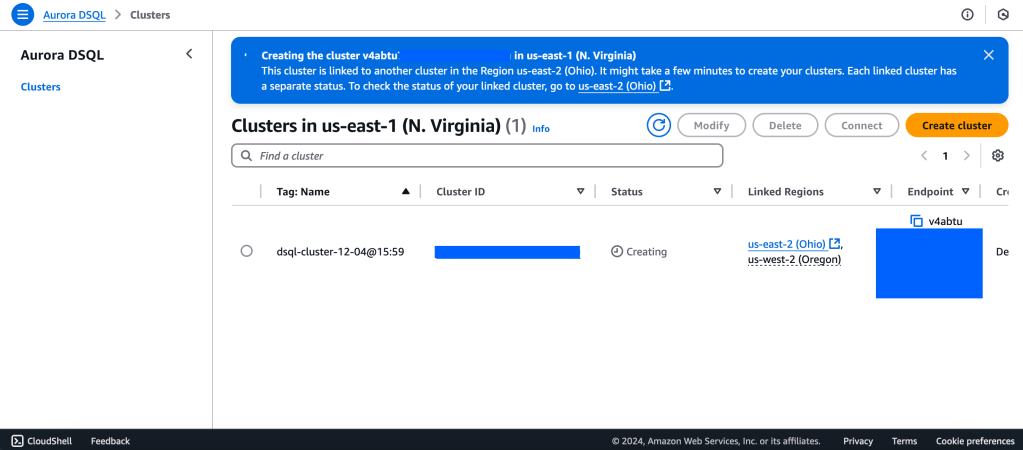
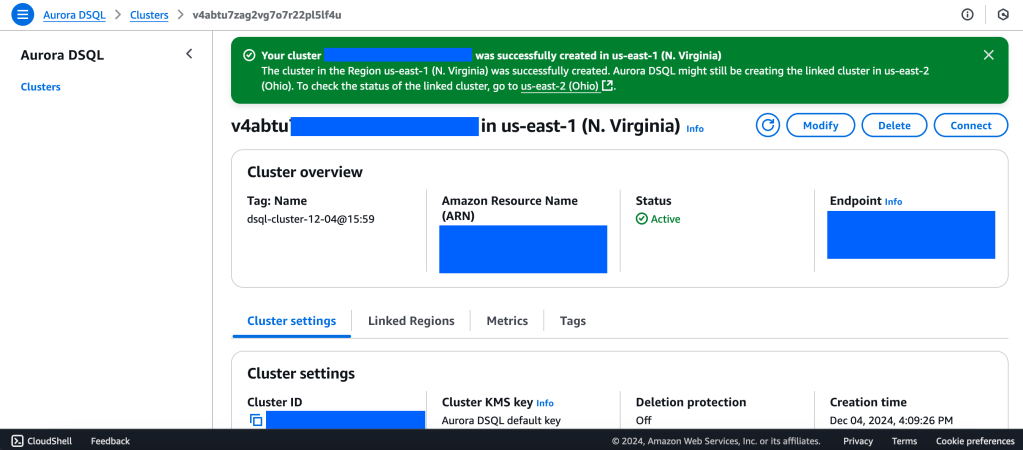
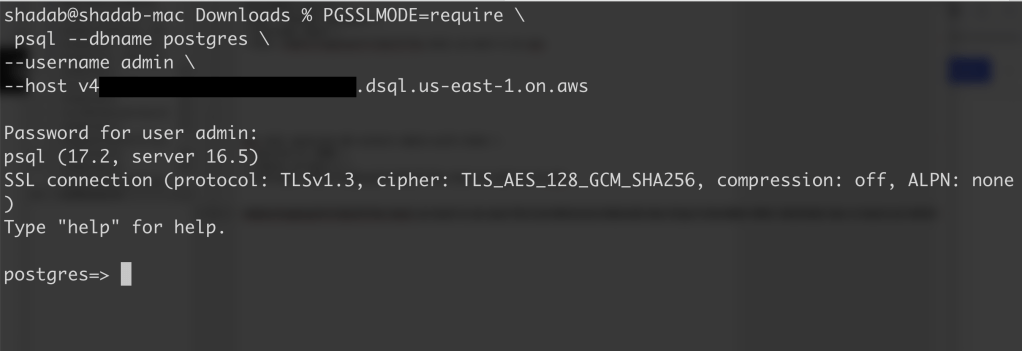
Aurora DSQL is already available as Public Preview in the US Regions. In this article I want to give you the first preview on creating a cluster and connecting to it with psql client.
Password for user admin: <paste-full-string-of-auth-token-output> psql (17.2, server 16.5) SSL connection (protocol: TLSv1.3, cipher: TLS_AES_128_GCM_SHA256, compression: off, ALPN: none) Type “help” for help.
\COPY app.orders (order_id,customer_id,product_id,product_description,order_delivery_address,order_date_taken,order_misc_notes) FROM ‘/Users/shadab/Downloads/sample_orders.csv’ DELIMITER ‘,’ CSV HEADER;
/* Try to wrap the command in a single-line */
6. Run SQL Query
[a] Query to Find the Top 5 Customers by Total Orders Within the Last 6 Months
WITH recent_orders AS ( SELECT customer_id, product_id, COUNT(*) AS order_count FROM app.orders WHERE order_date_taken >= CURRENT_DATE – INTERVAL ‘6 months’ GROUP BY customer_id, product_id ) SELECT customer_id, SUM(order_count) AS total_orders, STRING_AGG(DISTINCT product_id::TEXT, ‘, ‘) AS ordered_products FROM recent_orders GROUP BY customer_id ORDER BY total_orders DESC LIMIT 5;
[b] Query to Find the Most Common Delivery Address Patterns
SELECT LEFT(order_delivery_address, POSITION(‘,’ IN order_delivery_address) – 1) AS address_prefix, COUNT(*) AS order_count FROM app.orders GROUP BY address_prefix ORDER BY order_count DESC LIMIT 10;
[c] Query to Calculate Monthly Order Trends by Product
SELECT TO_CHAR(order_date_taken, ‘YYYY-MM’) AS order_month, product_id, COUNT(*) AS total_orders, AVG(LENGTH(order_misc_notes)) AS avg_note_length — Example of additional insight FROM app.orders GROUP BY order_month, product_id ORDER BY order_month DESC, total_orders DESC;
7. Check Latency
You can check latency from AWS Cloud Shell using traceroute to your Aurora DSQL endpoints from different regions
us-east-1 (N Virginia)
$ traceroute v*****u.dsql.us-east-1.on.aws
traceroute to v****u.dsql.us-east-1.on.aws (44.223.172.242), 30 hops max, 60 byte packets 1 * * 216.182.237.241 (216.182.237.241) 1.566 ms
ap-southeast-2 (Sydney)
$ traceroute v*****u.dsql.us-east-1.on.aws
traceroute to v********u.dsql.us-east-1.on.aws (44.223.172.242), 30 hops max, 60 byte packets 1 244.5.0.119 (244.5.0.119) 1.224 ms * 244.5.0.115 (244.5.0.115) 5.922 ms 2 100.65.22.0 (100.65.22.0) 4.048 ms 100.65.23.112 (100.65.23.112) 5.203 ms 100.65.22.224 (100.65.22.224) 3.309 ms 3 100.66.9.110 (100.66.9.110) 25.430 ms 100.66.9.176 (100.66.9.176) 7.950 ms 100.66.9.178 (100.66.9.178) 3.966 ms 4 100.66.10.32 (100.66.10.32) 0.842 ms 100.66.11.36 (100.66.11.36) 2.745 ms 100.66.11.96 (100.66.11.96) 3.638 ms 5 240.1.192.3 (240.1.192.3) 0.263 ms 240.1.192.1 (240.1.192.1) 0.278 ms 240.1.192.3 (240.1.192.3) 0.244 ms 6 240.0.236.32 (240.0.236.32) 197.174 ms 240.0.184.33 (240.0.184.33) 197.206 ms 240.0.236.13 (240.0.236.13) 199.076 ms 7 242.3.84.161 (242.3.84.161) 200.891 ms 242.2.212.161 (242.2.212.161) 202.113 ms 242.2.212.33 (242.2.212.33) 197.571 ms 8 240.0.32.47 (240.0.32.47) 196.768 ms 240.0.52.96 (240.0.52.96) 196.935 ms 240.3.16.65 (240.3.16.65) 197.235 ms 9 242.7.128.1 (242.7.128.1) 234.734 ms 242.2.168.185 (242.2.168.185) 203.477 ms 242.0.208.5 (242.0.208.5) 204.263 ms 10 * 100.66.10.209 (100.66.10.209) 292.168 ms *
# Generate fake data def generate_data(size): fake = faker.Faker() records = [] for _ in range(size): record = { 'CustomerID': fake.uuid4(), 'RecordDate': fake.date(), 'Name': fake.name(), 'Age': fake.random_int(min=0, max=100), 'Gender': fake.random_element(elements=('Male', 'Female', 'Other')), 'Address': fake.sentence(), 'Description': fake.sentence(), 'OrderID': fake.uuid4() } records.append(record) return records
def write_data_in_chunks(table_name, data, chunk_size): dynamodb = boto3.resource('dynamodb') table = dynamodb.Table(table_name) for i in range(0, len(data), chunk_size): with table.batch_writer() as batch: for record in data[i:i+chunk_size]: batch.put_item(Item=record) print(f"Successfully wrote {len(data)} records to {table_name} in chunks of {chunk_size}.")
if __name__ == "__main__": table_name = 'CustomerRecords' chunk_size = int(sys.argv[1]) if len(sys.argv) > 1 else 1000 data = generate_data(chunk_size) write_data_in_chunks(table_name, data, chunk_size)
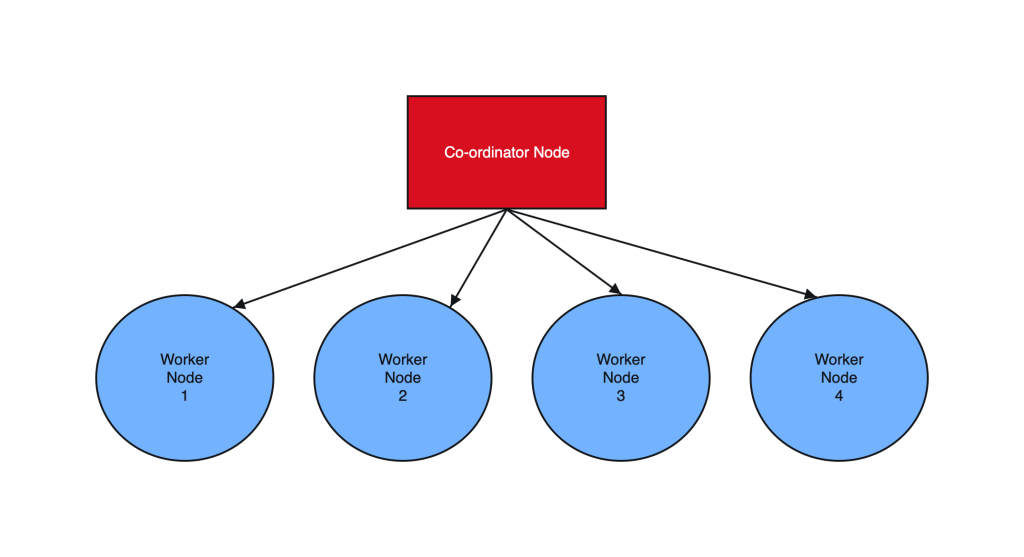
Postgres sharding with Citus is designed to horizontally scale PostgreSQL across multiple nodes. Citus extends PostgreSQL by adding the ability to distribute tables and queries across a cluster of servers.
Tables are horizontally partitioned into smaller, manageable shards that reside on different nodes. Each node contains a subset of the data and Citus intelligently routes queries to the appropriate nodes.
Sharding architecture enhances both read and write scalability, makes it well-suited for applications with growing data volumes and demanding workloads.
________________________ Step by Step Instructions to Setup Postgres Sharding ______________________________
Create OL8 or RHEL8 Instance and Run the below commands on all Nodes :
a. SSH into all the Instances and configure it as below :
sudo dnf module list postgresql

sudo yum -y install gnupg2 wget vim tar zlib openssl

sudo dnf install https://download.postgresql.org/pub/repos/yum/reporpms/EL-8-x86_64/pgdg-redhat-repo-latest.noarch.rpm

sudo yum -qy module disable postgresql

sudo yum install postgresql14-server -y

sudo yum install postgresql14-contrib -y

## Due to policies for Red Hat family distributions, the PostgreSQL installation will not be enabled for automatic start or have the database initialized automatically

sudo systemctl enable postgresql-14

sudo postgresql-14-setup initdb

sudo systemctl start postgresql-14

sudo systemctl status postgresql-14
b. Enable Postgres user and set Super user password
sudo -iu postgres

psql -c "ALTER USER postgres WITH PASSWORD 'RAbbithole1234#_';"

exit
c. Install Citus community edition binary and Create the Extension
# Add Citus repository for package manager

curl https://install.citusdata.com/community/rpm.sh | sudo bash

sudo yum install -y citus121_14
#Preload Citus and pg_stat_statements extensions on all Nodes

sudo -iu postgres

psql -U postgres -c 'SHOW config_file'

              config_file
----------------------------------------
 /var/lib/pgsql/14/data/postgresql.conf
(1 row)

vim /var/lib/pgsql/14/data/postgresql.conf

## Add below entry and uncomment 'shared_preload_libraries'

shared_preload_libraries = 'citus,pg_stat_statements'

## Note that “citus” has to be the first extension in the list. Otherwise, the server won’t start.

exit

sudo systemctl restart postgresql-14

sudo systemctl status postgresql-14


# Enable auto-start of Postgres 14 server when the server reboots

sudo chkconfig postgresql-14 on

sudo -i -u postgres psql -c "CREATE EXTENSION citus;"
sudo -i -u postgres psql -c "CREATE EXTENSION pg_stat_statements;"
d. Configure connection and authentication
sudo -iu postgres

vim /var/lib/pgsql/14/data/postgresql.conf

# Uncomment listen_addresses and set it as below
listen_addresses = '*'

# Uncomment and change wal_level = 'logical'
wal_level = 'logical'
vim /var/lib/pgsql/14/data/pg_hba.conf

# Change this line to allow all hosts 10.180.2.0/24 with trust
## Important Note : 10.180.2.0/24 is the subnet in which the instances reside. The subnet should have egress and ingress for the Postgres port. Alternately instead of doing a password-less setup, you can also use pgpass file to store the password on all nodes and use the normal authentication method. ##

# IPv4 local connections:
host    all             all             10.180.2.0/24           trust

exit

sudo systemctl restart postgresql-14

sudo systemctl status postgresql-14

## Whitelist Postgres Port##

sudo firewall-cmd --list-ports
sudo firewall-cmd --zone=public --permanent --add-port=5432/tcp
sudo firewall-cmd --reload
sudo firewall-cmd --list-ports
I’ve created a small automation script to perform the above steps. Save it as a .sh file, change the parameters according to your Postgres, citus version and simply execute on all the nodes:
#!/bin/bash

# Function to print commands and exit on failure
function run_command() {
    echo "$ $1"
    eval $1
    if [ $? -ne 0 ]; then
        echo "Error executing command. Exiting."
        exit 1
    fi
}

# Step 1: Install Postgres 14 Server on all Nodes
run_command "sudo dnf module list postgresql"
run_command "sudo yum -y install gnupg2 wget vim tar zlib openssl"
run_command "sudo dnf install -y https://download.postgresql.org/pub/repos/yum/reporpms/EL-8-x86_64/pgdg-redhat-repo-latest.noarch.rpm"
run_command "sudo yum -qy module disable postgresql"
run_command "sudo yum install postgresql14-server -y"
run_command "sudo yum install postgresql14-contrib -y"
run_command "sudo systemctl enable postgresql-14"

# Check if the data directory is empty
if [ -z "$(sudo -i -u postgres ls -A /var/lib/pgsql/14/data)" ]; then
    run_command "sudo postgresql-14-setup initdb"
else
    echo "Data directory is not empty. Skipping initialization."
fi

run_command "sudo systemctl start postgresql-14"
run_command "sudo chkconfig postgresql-14 on"

# Step 2: Enable Postgres user on all Nodes and set superuser password
run_command "sudo -i -u postgres psql -c \"ALTER USER postgres WITH PASSWORD 'YOurPassword1234#_';\""

# Step 3: Install Citus on all Nodes
run_command "curl https://install.citusdata.com/community/rpm.sh | sudo bash"
run_command "sudo yum install -y citus121_14"

# Step 4: Preload Citus and pg_stat_statements extensions on all Nodes
run_command "sudo -i -u postgres psql -U postgres -c 'SHOW config_file'"
run_command "sudo -i -u postgres sed -i -E 's/^#?(listen_addresses[ \t]*=[ \t]*).*/\1'\''*'\''/' /var/lib/pgsql/14/data/postgresql.conf"
run_command "sudo -i -u postgres sed -i -E 's/^#?(shared_preload_libraries[ \t]*=[ \t]*).*/\1'\''citus,pg_stat_statements'\''/' /var/lib/pgsql/14/data/postgresql.conf"
run_command "sudo -i -u postgres sed -i -E 's/^#?(wal_level[ \t]*=[ \t]*).*/\1'\''logical'\''/' /var/lib/pgsql/14/data/postgresql.conf"
run_command "sudo -i -u postgres sed -i -E '/^# IPv4 local connections:/ { n; s/^(host[ \t]*all[ \t]*all[ \t]*)127.0.0.1\/32[ \t]*scram-sha-256$/\10.0.0.0\/0           trust/ }' /var/lib/pgsql/14/data/pg_hba.conf"

# Step 5: Configure connection and authentication on all Nodes
run_command "sudo systemctl restart postgresql-14"
run_command "sudo firewall-cmd --list-ports"
run_command "sudo firewall-cmd --zone=public --permanent --add-port=5432/tcp"
run_command "sudo firewall-cmd --reload"
run_command "sudo firewall-cmd --list-ports"

# Step 6: Create Citus extension on all Nodes
run_command "sudo -i -u postgres psql -c \"CREATE EXTENSION citus;\""
run_command "sudo -i -u postgres psql -c \"CREATE EXTENSION pg_stat_statements;\""

echo "Script execution completed successfully."
2. Create Co-ordinator and Worker nodes
We have now prepared 3 instances for sharding in total. Step 1 should have been performed on all the below instances :
All steps below to be executed from Co-ordinator node :
CREATE TABLE orders (
order_id    bigserial,
shard_key   int PRIMARY KEY,
n           int,
description char(100) DEFAULT 'x');

# Create Index to further optimize the SQL performance
CREATE UNIQUE INDEX shard_key_idx on orders (shard_key);

# Add Distributed table
SELECT create_distributed_table('orders', 'shard_key');

\timing

# Generate 5 Million rows
INSERT INTO orders (shard_key, n, description)
SELECT
    id AS shard_key,
    (random() * 1000000)::int AS n,
    'x' AS description
FROM generate_series(1, 5000000) AS id
ON CONFLICT DO NOTHING;


#Check the Size of the table using the Citus Table and not Standard Postgres comman
\x
SELECT * FROM citus_tables ;

# Check Explain plan of Query
\x
explain (analyze, buffers, timing) SELECT count(*) from orders;
explain (analyze, buffers, timing) SELECT count(*) from orders where shard_key=2 ;
4. Add another node by performing all commands in Step 1. and add it to the cluster
IP : 10.180.2.17
Run from the Co-ordinator node
sudo -i -u postgres psql -c "SELECT * from citus_add_node('10.180.2.17', 5432);"

sudo -i -u postgres psql -c "SELECT * FROM citus_get_active_worker_nodes();"

  node_name   | node_port
--------------+-----------
 10.180.2.198 |      5432
 10.180.2.86  |      5432
 10.180.2.17  |      5432
(3 rows)

# Add .pgpass file on co-ordinator node and add the DB details >> hostname:port:database:username:password
vim /var/lib/pgsql/.pgpass

localhost:5432:postgres:postgres:YOurPassword1234#_

chmod 600 .pgpass

# Re-balance the shards without downtime
psql -U postgres -h localhost

ALTER SYSTEM SET citus.max_background_task_executors_per_node = 2;
SELECT pg_reload_conf();
SELECT citus_rebalance_start();

NOTICE:  Scheduled 10 moves as job 1
DETAIL:  Rebalance scheduled as background job
HINT:  To monitor progress, run: SELECT * FROM citus_rebalance_status();
 citus_rebalance_start
-----------------------
                     1

#Check Status of rebalancing
SELECT * FROM citus_rebalance_status();

      1 | running | rebalance | Rebalance all colocation groups | 2023-12-24 09:44:16.813663+00 |             | {"t
asks": [{"LSN": {"lag": null, "source": "0/371A5128", "target": null}, "size": {"source": "29 MB", "target": "26 MB
"}, "hosts": {"source": "10.180.2.198:5432", "target": "10.180.2.17:5432"}, "phase": "Catching Up", "state": "runni
ng", "command": "SELECT pg_catalog.citus_move_shard_placement(102012,2,4,'auto')", "message": "", "retried": 0, "ta
sk_id": 4}], "task_state_counts": {"done": 3, "blocked": 6, "running": 1}}
(1 row)

#Once completed the output will be as below :

SELECT * FROM citus_rebalance_status();

 job_id |  state   | job_type  |           description           |          started_at           |          finishe
d_at          |                     details
--------+----------+-----------+---------------------------------+-------------------------------+-----------------
--------------+--------------------------------------------------
      1 | finished | rebalance | Rebalance all colocation groups | 2023-12-24 09:44:16.813663+00 | 2023-12-24 10:18
:24.886163+00 | {"tasks": [], "task_state_counts": {"done": 10}}

# Check the Shard views
SELECT * from pg_dist_shard;
SELECT * FROM citus_shards;

#Misc rebalancing SQL queries
select get_rebalance_table_shards_plan();
SELECT citus_set_default_rebalance_strategy('by_disk_size');
SELECT * from citus_remote_connection_stats();